AI 越来越强,人们正在让渡思考和判断:Claude 工程师 Addy Osmani 的防「认知投降」手册
原文链接: https://x.com/addyosmani/status/2117512471930167377 来源: x.com 发现于: 小互 · AI 解读站 · 2026/11/4 说明: 本文由 AIHot 自动聚合(原文即中文,未翻译)。正文取自小互 AI 解读
全文 Markdown · 会员
作者:Addy Osmani11-04 · 约 7 分钟⚑ 大佬观点 · 个人立场🎧 听播客版0:00 / --:--
视频/音频
0:00 / --:--
AI 替人干活越干越好,有一样东西却在悄悄流失:我们自己的判断。它不是哪天突然被交出去的,而是在一次次「看着没问题」之后,被顺手交了出去。
过去从提出问题到拿到答案,中间要查、要想、要掂量,判断力就是在这段路上磨出来的。现在这段路缩成了几秒。模型又越来越强,明显的错越来越少,交回来的东西格式漂亮、大体正确,根本不会逼你再看第二眼。它错得少了,看的人也就松了。
办法当然不是少用 AI。该交的照样交,难的是分清哪些交出去还归你,哪些一交就再也收不回来。
Claude Code 团队的工程师 Addy Osmani 专门写了一篇长文讲这件事。他自己整天同时开着好几个 Agent 干活,看到的危险是:人会从「让 AI 打工」一路滑到「认知投降」,而且一路都不自知。他给的判断线很干脆:「如果你连借助 Agent 都解释不了答案,你就已经交出了所有权。」
这种下滑之所以难以自己刹住,是因为这套工作流实在太舒服。忙了一整天,又快又顺、多半还对的答案让人如释重负,戒备心偏偏就在这时候卸下。可你后台挂再多 Agent,盯着结果的眼睛也只有你这一双。默认情况下,没有任何东西会替你停下来想一想,这一步只能你自己排进每天的工作里。

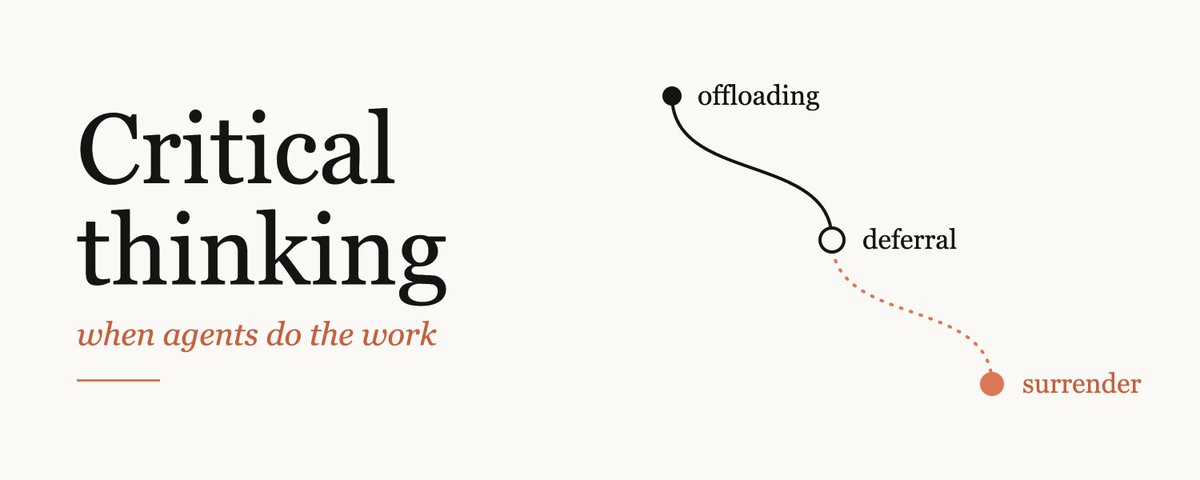
原文头图:offloading(委托)→ deferral(顺从)→ surrender(投降),虚线那段就是没人察觉的下滑。
从委托到投降,每一步都看着合理
把活交给 AI,可以分成三档。最上面是认知委托:活交出去了,结果还归你,你知道它干了什么,也能为它负责。中间是顺从:AI 的输出直接成了你下一步的输入,不再被当成一个有待验证的猜想。最底下是认知投降:AI 的输出悄悄变成了你自己的想法,你压根不觉得需要检查。「认知投降」这个词出自沃顿商学院的 Steven Shaw 和 Gideon Nave。
顶部
认知委托
活交给 AI,结果还是你的:你知道它干了什么,能为它负责。Addy 一整天都这么干,也建议你这么干。
中间
顺从
AI 的输出成了你下一步的输入,不再是「待验证的猜想」,被当成了事实。
底部
认知投降
AI 的输出悄悄变成你自己的想法,你完全不觉得有必要检查。
下滑是怎么发生的:每一步都很合理
- 上一个答案认真读了挺好,于是……
- 下一个扫了一遍也挺好,于是……
- 再下一个只看骨架然后某天……
- 有人指着一行问,你解释不了哪怕让 Agent 帮你一起解释也不行。这就是认知投降。
可怕的不只是落到哪一档,而是往下滑没有声音。上一个答案你读得很认真,于是下一个扫一眼,再下一个只看个骨架,每一步都说得过去。直到有人指着其中一行问为什么,你才发现自己讲不出来,叫上 Agent 一起也讲不出来。
这样欠下的叫认知债,平时一点都看不出来:代码库整整齐齐,测试全部通过;只看了目录就签字放行的需求文档,也一样体面。要等你得动这套系统、得凭自己的理解推一件事时,才发现那份理解根本不存在。放到团队里,是大家对系统「怎么运作」的共同认识被一点点磨没;落到代码上,就是 Jeremy Twei 说的「理解债」。
但别把这条线读成「什么都得懂」。大型代码库谁也装不下全貌,Claude Code 团队自己就是按需重建理解:要动哪一块,就让 Claude 把那一块讲给自己听。这种债比多数工程师以为的好还,前提是你知道自己缺的是哪一块。所以红线只有一条:借助 Agent 都讲不清,才算真正交出去了。
能不能整个交出去,看错了谁买单
交出去本身不是坏事。Addy 前阵子录课,要从三家评分差不多的酒店里挑一家当录制地点,他没空翻评论,就把决定交给了 AI,结果没问题,下次还会这么干。可家里的钱怎么投、怎么给孩子的职业出主意,他不会这样定;工作上做什么、哪些改动会影响哪些用户、能不能放心上线,也不会。
可以整个交出去
错了也不贵
三家评分接近的酒店选哪家。选错代价很小,后果也只落在自己头上。
推理留在手里
后果别人来扛
家里的钱怎么投、怎么给孩子的职业选择提建议;工作中做什么、哪些改动影响哪些用户、能不能安全上线。
错了也不贵的事,放手交接;后果要别人承担的事,推理留给自己。
Take the handoff where being wrong is cheap, keep the reasoning where others will have to deal with the consequences.
动手之前,先给自己一个猜测
以前想不清楚一件事,人会翻出一张很土的清单:我在解决对的问题吗?方法对吗?结论有证据吗?怎么知道已经做完了?写出来幼稚得可笑,却能逼你想到平时漏掉的角度。现在跳过这一切太容易了,一句「你觉得我该怎么做」就够了。
新版的清单是这六个问题:
- 提问之前,我自己猜过答案吗? 猜得再烂也行,有了新信息随时改。一旦先读了一个写得漂亮的回答,你就很难再想象别的可能。实在没头绪,就用 Thariq Shihipar 说的「盲点扫描」:把你知道的告诉模型,让它帮你找出你不知道自己不知道的东西。
- 我是让它帮我想,还是把思考整个甩给它? 两种都行,只要你清楚自己在做哪一种。
- 要让这个结论是错的,什么条件必须成立? 然后去查。模型对自己有几成把握的自评,远不如一个你能实际跑一遍的测试。
- 我听过反方的意见吗? 立场已经很坚定的开放问题,就让不止一个模型替对立的一方辩护,读完再下结论。费时间,但最后懂得多得多。
- 当着以后要维护它的人,我敢为它打包票吗? 代码如此,交付的任何东西都如此。这就是「能不能负责」的标准线。
- 我已经不再练哪些事了? 比如一些日常排错。放掉一部分可以,但最好是有意识的选择。
绿勾不等于做完,先看证据再看总结
瓶颈已经从「写代码」转到了「确认自己是对的」。给 Agent 一个检验自己工作的手段,端到端测试、属性测试,或者真去点一遍应用,它就能改一处、跑一遍、读结果、再试,这些都在你看之前完成。Claude Code 的创建者 Boris Cherny 把这叫「给 Claude 一个验证自己工作的方法」。你的活也跟着变了:不再逐行读,而是搭好这些循环,审查它留下的证据。
麻烦在于,验证本身也会被投降掉。「结论有证据吗」不知不觉就变成了「检查变绿了吗」。Agent 让写测试便宜到几乎不要钱,满屏绿色随手就有,可绿色和「功能是好的」之间还隔着几道坎。
满屏绿勾里的两个陷阱,和一个该问的问题
同一个错**测试和功能犯了同一个错。写测试时带着写功能时同样的误解,测试照样通过,功能照样是坏的。 只证一件事一个绿勾只证明一件事。人却很容易以为它覆盖了所有方面。 该怎么问绿勾亮了,先问它证明了什么,**再问它没证明什么。
几个让证据站得住的习惯:
- 标准事先定,做完再定只会替结果找理由。
- 终点要摸得着:一个通过的测试、一张截图、一段日志。「做完了」是事实,不是一种感觉。
- 收到「已完成」,先别看总结,先看它实际跑了哪些命令、输出了什么。
- 让一个全新上下文的子 Agent 挑毛病,固定进流程,每次都跑,而不是想起来才跑。
- 最后问一句「我漏了什么吗?」 听着有点傻,但 Addy 用前沿模型做完复杂功能、自己审过之后再这么问,它常常还能再找出两三件事,所以他每次都问。
不是每件事都要这样深挖,知道什么时候该深挖本身就是本事。Claude Code 团队写代码审查的那篇文章里有条经验法则:说不出这些检查会漏掉什么,就去要一次真正的审查,别快速批准。
这套道理出了代码一样成立。Agent 替你汇总了五十通客户电话,或者做了份竞品分析,就去翻几份原始材料,看总结准不准;你的建议押在某个数字上,就核一遍它算对没有。搭验证已经很便宜了,难的是你得知道好的验证长什么样。
审改动,更要审它替你做的决定
设想 Agent 交给你一个 600 行的代码合并请求。你看了看结构,没逐行读,变量名挺像回事,测试也过了,于是点了批准。可中间某处,事务里几步操作的先后顺序被悄悄调了,或者某个你从没想到的边缘情况下,默认值被反了过来。你确实审过了,只是你只找了自己本来就知道要找的那些。
写代码和审代码是两门手艺,审着审着就成了盖章。
第一层
读改动
把改动当成不是 AI 写的那样去读,不因为「反正是 AI 写的」就降低标准。
第二层,更容易漏
读它替你做的决定
长时间工作里,Agent 会替你做大量小决定:用了什么默认值,认定什么不在范围内,两条需求冲突时改写了哪条。
这些决定在一份「一切顺利」的总结里全都看不见,所以要逼它摊开:
- 让它把自己做过的决定和假设列出来。
- 然后考自己:随手挑几行,这行在干什么?那行呢?如果是文档,就合上它,凭记忆写出主要论点。
- 长会话结束时,让 Claude 就这次改动写份报告,末尾附一套测验题,规矩是「测验全对,才合并」。
你得把交付的东西理解到能替它辩护的地步,因为迟早有人会问。
Agent 也能帮你守住注意力。Addy 维护的开源项目常常涌进大量代码合并请求,他用 Agent 判断进来的都是什么、哪些违反了项目规范、哪些需要他亲自看。它很少替他拍板,但能把范围缩到他该看的地方,他才腾得出脑子去想:这个改动是不是用对的方法解决了对的问题。
最后是产量,这一点得对自己诚实。Agent 们产出的东西,和你愿意署上自己名字的东西,中间有一道差距,Addy 管它叫编排税。做完的活堆得比你看得快,再开一个会话也无济于事:要么收紧检查,让需要你过目的东西少一点,要么就慢下来。
当你产出的东西多过你能担保的,你就不是在审查了,你是在祈祷。
人脑没被替掉,只是挪到了两头
理解仍然在干活,只是从中间挪到了开头和结尾:开头交代任务和背景,结尾审查结果。所以输入的质量决定输出的质量,写好提示词本身就是一项批判性思考能力。
开头
把任务说清楚
给谁用、什么不做、怎样算完成。说不清,往往是自己还没想清。
结尾
把结果审清楚
看证据、读它做的决定,不愿署名的不发出去。
中间的活交给 Agent;原来散在过程里的思考,现在要集中花在这两端。
开头这一端,最容易欠下的是意图债。过去你提一个含糊的需求,总有人追问,你才猛然意识到:这事我其实还没想清楚。Agent 一般不会拦你,它会把你没说的部分自己补齐,交回一个看起来做完了的东西,背后的想法依然是糊的。目标、约束、理由,这些藏在你没亲手写的成果里的东西,别人替你还不了,只能你自己来。
- 求助之前,先用自己的话写一份简短需求:给谁用、哪些不做、怎样算完成。
- 改了两轮还没到想要的结果,就别再修修补补了,重写提示词。
- 把它当合作者而不是承包方。哲学家 Andy Clark 区分过「把事委托给 AI」和「跟它合作」:合作时你的提示词让输出更好,输出又让你下一条提示词更准、对问题想得更清楚。还想不清,就让 Agent 来采访你,问它没搞懂的地方。会话结束时你比开始时更明白,就是成功。
- 提防总结接力:每个 Agent 都只拿上一个 Agent 的总结当上下文,传到第三个,就已经没人读过原始文档了。
结尾这一端,你得有自己的标准。如今什么东西出来都格式漂亮、语气笃定,「看起来很精致」已经不算信号了。Addy 在各种创作形式里试过 AI,大部分成果从没拿出来见人,因为没过他自己那关。他的线是:不愿署上自己名字的东西,就不发出去。
没过线的东西,把原因写进共享配置、一个 Hook 或一条测试,让同样的问题不再出现。品味就是这么一点点攒出来的,把「为什么没入选」记下来,本身就是很好的练习。
模型再强,责任也交不出去
读到这里,你多半冒出过这个念头:再过一两年,模型能发现的问题就和我一样多了,我何必还练这些?
在「发现问题」上,你可能大体是对的,越来越多的检查本来就该交给 Agent。但这项能力还得留着,理由有三条:
- 总得有人为上线的东西负责。 AI 帮了再多忙,最后签字担责的还是一个人。
- 该信它多少,本身就是判断。 模型出错的地方一直在变,只有持续审查它的活,这个判断才准。Anthropic 研究自家工程师时把这叫「监督悖论」:监督 Claude 所需要的,恰恰是那些可能因为过度用 AI 而退化的编程技能。
- 有些问题模型再强也替你答不了: 你在做什么?为什么值得做?会影响谁?你愿意为它放弃什么?Agent 可以陪你想,答案终归是你的。
活可以交出去,大部分检查也可以交出去,但责任交不出去。
不练的技能,消失得比你想的快
不练的技能会消失,而且比你想的快。你不愿放掉的那些,就一直练着。下面这些不必全盘照做,挑适合自己工作流的就行。
每周不用 Agent 写一点代码,或做一件「要是忘了怎么做就糟了」的事。他管这叫校准练习,并说明这不是道德要求。 每月写下你已经不再做的事,逐一决定哪些可以放掉。再问自己:如果 AI 不存在了,你会有多迷茫? 遇到时碰到看不懂的说法,别搜一句解释塞进去,花点时间真正搞懂,看清它在整体里的位置。 排期好好检查 Agent 的产出是真实工作量。假装它不花时间,团队最后就不会做。把它当正式工作项排进计划。
这篇真正值得带走的
- 危险不在 AI 错得多,而在它错得少。 错少了人就不看,判断在一次次「看着没问题」里交了出去。分辨的红线只有一条:借助 Agent 还讲不讲得清。
- 人脑的位置挪了,没被替掉。 开头写清意图,结尾守住标准,中间才放心交给 Agent。
- 证据和决定,比总结重要。 先看它跑了什么、替你决定了什么,再看它说自己做成了什么。
下面这段可以直接贴在任务末尾,8 条清单留着下次交任务前勾一遍。
贴在任务末尾
完成之后、写总结之前,请按顺序给我:
1. 你替我做的所有决定和假设:用了哪些默认值、你认为哪些不在范围内、需求冲突时怎么取舍的。
2. 你实际运行的检查命令,以及它们的原始输出。
3. 这些检查证明了什么,没有证明什么。
4. 针对这次改动出 5 道测验题,不附答案。我全部答对才采用这个结果。
Addy 的 8 条,下次交任务前对照勾一勾
- 有意为之Agent 能考你、采访你、给你看证据,前提是你把这些设置好。
- 诚实看自己在光谱哪一档借助 Agent 都解释不了答案,就是已经投降了。
- 先有猜测提问前先形成一个,哪怕很烂。
- 一个绿勾只意味着一件事它检查了什么?没检查什么?
- 找证据先读它运行了什么、返回了什么,再读总结。
- 读出它替你做的决定它替你决定了什么?
- 认真写提示词你怎么写,暴露了你对问题懂多少。
- 设一条线,守住它不愿署名的,就不发出去。
Addy 留了个小作业:提问之前,写下你觉得会发生什么;Agent 做完之后,写下一件它没有检查的事。试一次,看看你读它输出的方式会不会变。

原文文末附的 AI 文本检测结果:人工 90%,AI 10%。
来源Critical thinking when agents do the workAddy Osmani·查看主材料
Addy Osmani · Claude Code
AI 越来越强,人们正在让渡思考和判断
AI 替人干活越干越好,有一样东西却在悄悄流失:我们自己的判断。它不是哪天突然被交出去的,而是在一次次「看着没问题」之后,被顺手交了出去。
核心红线:如果你连借助 Agent 都解释不了答案,你就已经交出了所有权。
过去从提出问题到拿到答案,中间要查、要想、要掂量,判断力就是在这段路上磨出来的。现在这段路缩成了几秒。模型又越来越强,明显的错越来越少,交回来的东西格式漂亮、大体正确,根本不会逼你再看第二眼。它错得少了,看的人也就松了。
办法当然不是少用 AI。该交的照样交,难的是分清哪些交出去还归你,哪些一交就再也收不回来。
核心滑坡:从「让 AI 打工」到「认知投降」的三档位移
危害最隐蔽的地方在于:往下滑没有声音,每一步都显得无比合理。直到被问到为什么,才发现自己和 Agent 都讲不清楚。
01 认知委托 · Offloading 所有权仍归你
活交出去了,结果还归你,你知道它干了什么,也能为它负责。动哪一块就让它讲哪一块,缺什么补什么。
02 顺从 · Deferral 未经验证直接采纳
AI 的输出直接成了你下一步的输入,不再被当成一个有待验证的猜想。只看格式整齐就签字放行,戒备在舒适中卸下。
03 认知投降 · Surrender 丧失所有权
AI 的输出悄悄变成了你自己的想法,你压根不觉得需要检查。代码整齐、测试全过,背后的真实理解却已不复存在。
Addy Osmani 的所有权红线 「如果你连借助 Agent 都解释不了答案,你就已经交出了所有权。」
可以整个交出去:错了也不贵
- 三家评分差不多的酒店挑哪家。选错代价很小,后果也只落在自己头上。
推理留在手里:后果别人来扛
- 家里的钱怎么投、怎么给孩子的职业出主意;工作上做什么、哪些改动影响哪些用户、能不能放心上线。
错了不贵的事,放手交出去;后果要别人承担的事,推理留在自己手里。
结构重构
人脑没被替掉,只是挪到了两头
理解仍然在干活,只是从中间挪到了开头和结尾:开头交代任务和背景,结尾审查结果。写好提示词本身就是一项批判性思考能力。
开头:交代意图与约束
警惕「意图债」 过去需求含糊总有人追问;Agent 不会拦你,会自行脑补做完,但背后的想法依然是糊的。
- **先猜后问:**求助前先自己猜一个答案;实在猜不出,再用盲点扫描找出「不知道自己不知道」的东西。
- **合作而非外包:**两轮修补不对就重写提示词;让 Agent 采访你没交代清楚的目标与约束。
结尾:守住标准与证据
警惕「编排税」 做完的活堆得比你看得快。当你产出的东西多过你能担保的,你就不是在审查了,你是在祈祷。
- **署名底线:**不愿署上自己名字的东西,就不发出去;没过线的原因写进共享配置、Hook 或测试。
- **考考自己:**文档就合上它,凭记忆写出主要论点;代码改动就让 Claude 出一套测验题,测验全对才合并。
哲学家 Andy Clark 区分过「把事委托给 AI」和「跟它合作」:合作时你的提示词让输出更好,输出又让你下一条提示词更准、对问题想得更清楚。
审查实践
绿勾不等于做完:先看证据与决定,再看总结
Agent 让写测试便宜到几乎不要钱,满屏绿色随手就有,可绿色和「功能是好的」之间还隔着几道坎。瓶颈已经从「写代码」转到了「确认自己是对的」。审查必须穿透表面总结,直击核心决定。
查命令与日志 **收到完成先别看总结:**先看它实际跑了哪些命令、输出了什么。终点要是摸得着的测试、截图或日志。
摊开隐性决定 **逼它列出决定与假设:**比如事务里的操作顺序被调了、边缘情况的默认值被反了,这些在「一切顺利」的总结里都看不见。
全新上下文挑错 **子 Agent 挑毛病:**让全新上下文的子 Agent 专挑漏洞,固定进流程、每次都跑;最后再问一句「我漏了什么吗?」。不是每件事都要深挖:说不出这些检查会漏掉什么,就去要一次真正的审查。
日常练习
不练的技能,消失得比你想的快
你不愿放掉的那些,就一直练着。不必全盘照做,挑适合自己工作流的就行。
每周不用 Agent 写一点代码,或亲手做一件「要是忘了怎么做就糟了」的事。 每月写下已经不再做的事,决定哪些放掉也无所谓;再问自己:如果 AI 不存在了,你会有多迷茫? 排进计划认真检查 Agent 的产出是实打实的工作,把它当正式任务排期,不然团队最后就不会做。
底线认知
模型再强,责任也交不出去
再过一两年模型能发现的漏洞可能和人一样多,但人脑判断仍然不可或缺:总得有人为上线的东西负责;而在具体场景该信它多少,本身就是一种动态判断。
一个人 AI 帮了再多忙,最后签字担责的还是一个人
监督悖论 审查 AI 所需的能力,恰恰可能因过度用 AI 而退化
4 个问题 模型替你答不了:在做什么、为什么值得做、会影响谁、愿为它放弃什么
核心值得带走的三条法则
- **危险在错得少:**明显的错少,警惕心就散;判断在一次次「看着没问题」里交了出去。红线只有一条:借助 Agent 还讲不讲得清。
- **人脑挪到了两头:**开头写清意图与边界防「意图债」,结尾守住标准与证据防「编排税」,中间才放心交给 Agent。
- **先证据后总结:**先看跑了什么、替你决定了什么,再看它宣称做成了什么。
原文版权归原作者,这里只供对照阅读。 看原网页 ↗
Critical thinking when agents do the work
Back in the day, critical thinking was taught as approaching new info with humble curiosity and a healthy dose of skepticism - take in different views, form your own opinion. Still true, but increasingly, nothing in my day-to-day forces critical thinking on me now that so much of my work runs through agents. For the engineers and product people who have fully bought into agentic workflows (running multiple sessions in parallel and expecting the models to improve), I'm here to say: I'm a big fan of these tools. I'm not writing this to advocate for less agentic workflows.
My goal is to help you maintain critical thinking in a world where it's easy to offload anything to an agent.
In the past, most of our cognitive and aesthetic processing happened in the space between question and answer. That space is now measured in seconds. The more you use agentic workflows, the more difficult it becomes (though not in the way I think people expected): as the models improve, the percentage of obvious errors is lower. Many (most?) outputs will be well-written and mostly correct, but they won't demand a second look.
Even if you are running many agents at a time, you still only have one pair of eyes on the outputs.
You have to build critical thinking into your day, because by default nothing will do it for you.
Part of the reason it's hard to self-correct for this is that agentic workflows are pleasant. Getting fast, pleasant, often-correct answers is refreshing in a busy day, but that's also why it's easy to relax your vigilance.
Offloading, deferral and surrender
When discussing this with people, I describe it as a spectrum:
At the top: cognitive offloading, the act of delegating tasks to the AI, but maintaining ownership of the result. I do this all day. You should, too. In the middle: deferral, where the output of the tool becomes your new input; the result has ceased to be a hypothesis. At the bottom: cognitive surrender - the AI's output quietly becomes your own, you feel no need to check it.
Cognitive surrender is a term coined by Steven Shaw and Gideon Nave at Wharton. It fits neatly what I've been seeing: as trust (or laziness) increases, people drift down the spectrum. The transition is rarely observed, because the steps are each gradual and seem reasonable. You read the last answer well, so you skim the next one. You just scan the skeleton of the one after that. Then you get asked about a line and can't explain it, even with your agent's help.
That's cognitive surrender. It's how cognitive debt accumulates. It's usually discovered when you try to apply a mental model of the system and it doesn't exist. Margaret-Anne Storey has written about how this shows up in teams as an eroding understanding of a shared system theory. I've written about the code equivalent, comprehension debt (a term coined by Jeremy Twei). In the moment, it's completely invisible. The codebase looks pristine and the tests pass. It doesn't become obvious until you have to make a change to the system and realize that nobody understands it anymore. The same applies when you've read the table of contents of a strategy doc or spec and signed off on it.
To be clear, I'm not advocating for the impossible. It's impossible to maintain the full mental model of a large modern codebase.The Claude Code team has said publicly that they rebuild understanding on demand: when they need to understand a part, they ask Claude to explain that slice, rather than holding the full model in their heads. As I'vewritten about before, this sort of debt is more recoverable than most engineers expect. You don't need to maintain the full model as long as you can rebuild it locally as needed. You just need to know what you don't have.
Where the stakes are low, feel free to delegate entirely. When you can't explain the answer to a question, even by way of your agent, you've ceded ownership.
This isn't always a problem, either. Just recently, I was recording a course and had to select one out of three similarly-rated hotels to use as a recording location. I didn't have time to manually review all the reviews, so I delegated the decision to an AI. It worked, and I'd do the same thing again. However, I wouldn't do that when deciding how to invest our money, how to advise our kids on their careers, or at work: what we should build, what changes affect what users, whether it's safe to ship. Take the handoff where being wrong is cheap, keep the reasoning where others will have to deal with the consequences.
The questions I ask myself
When I didn't know what I thought, I'd usually go back to a basic list of questions like these: How do I know that I'm working on the right problem? How do I know that I'm solving it the right way? Is there evidence that supports my conclusion? How do I know that I'm finished? Most times, this is just who, what, where, why, when and how. When written out, it looks absurdly child-like, but it forces you to think in terms of categories that you'd otherwise ignore. These days, it's too easy to simply skip all of this and ask your agent what it thinks you should do. These are the new versions of these questions that I ask myself now.
Did I formulate a hypothesis before asking? Before I run an agent on any non-trivial task, I write down, even just in my head, what I think the answer might be. It's OK if it's a bad guess. You're always welcome to change your mind in light of new information. Once you've read a well-written response, though, it's hard to imagine any other possibility. If you have no guidance whatsoever, ask for what Thariq Shihipar calls a blind spot pass: give the model what you know and have it find your unknown unknowns.
Am I asking it to help me think or to offload thinking from me? Both are OK, as long as you know which one you're doing.
What would have to be true for this to be wrong? Then go find out. A model's self-assessment of confidence is much less valuable than an actual test you can perform, so give it one.
Have I heard the counter argument from a different angle? When I've taken a hard stance on something that's somewhat open-ended, I'll ask more than one model to argue the opposite side, then review the output and form my own opinion. This takes longer, but I end up knowing much more about the subject.
Would I bet on this in front of the person who has to maintain it? This applies to code and to anything else that you're delivering. I believe that this is the bar for answerability.
What am I no longer practicing? Maybe it's some of the routine debugging. I'm OK with letting some of that go, but I want it to be intentional.
Verification as a habit
I've been writing a lot about verification lately because I believe that the bottleneck has shifted from coding to being sure you're right. When you give an agent the means to verify what it's doing, whether that be by way of end-to-end tests, property tests, or by way of actual app interactions, it can make a change, run the verification test, read the output, and attempt again all before you've looked at anything. This is what Boris Cherny calls "give Claude a way to verify its work" and I believe that this is one of the most critical components of achieving great results. Rather than reading every line, you'll be building these loops and reviewing the evidence.
You can also surrender verification. "Is there evidence that supports my conclusion?" becomes "Did the check turn green?" Agents make it so cheap to create tests that you'll see a lot of green, and you could have a passing test that doesn't catch a broken feature. If the test is written with the same mistake as the feature, it'll pass. And a green check only conveys one property. It's too easy to imagine it covers everything.
When a check goes green, ask what it proved. Then ask what it didn't.
Define "verified" upfront, because post-facto, you'll rationalize any outcome.
The finish line for agent work should be something tangible: a test passing, a screenshot, a log or trace. This ensures that the criteria for finishing the work is factual, and not up for interpretation (and surrender) based on something like "it looks like it's done." When you receive a finish notification from an agent, before you look at the summary, first review the code snippet of the command executed and its output.
Claude Code can also self-critique (via a subagent in a fresh context) its own work as a sanity check, and it's worth baking that into the loop so it runs every time, not just when you remember. I still ask at the end "Did I miss anything?" That sounds silly, but so often, when I finish some complex feature work using a frontier model, look at it, review it, and then ask, "Did I miss anything?" It will then come back with two or three more things. That's why I always ask.
None of this needs to be the norm, of course; knowing when to go deep is a skill. My favorite rule of thumb from our write-up on how the Claude Code team does code review is: "If you can't say what the checks would miss, ask for a real review rather than a quick approval."
This applies beyond code as well. If an agent has synthesized fifty customer calls for you, or a competitive analysis, check a couple of the source documents to make sure the summary is accurate. Check a number that your recommendation depends on to make sure it's being calculated correctly.
Agents have made verification cheap to set up. What's difficult for you is knowing what good verification looks like.
Actually paying attention to what's generated
Say an agent gives you a 600-line PR. You roughly look at the structure. You don't read every line. The variable names look reasonable and the tests pass, so you approve it. But somewhere in the middle there's a subtle ordering change in a transaction boundary, or a flipped default on an edge case you never thought about. You did review it, I guess, but only for what you already knew you'd find.
Writing code and reviewing it are different skills, and there's a point where reviewing turns into rubber stamping. So read the diff as if the AI didn't write it, and then look past the diff at what the agent decided. Over a long session it makes a lot of small decisions for you: the defaults, what's out of scope, which requirement it reinterprets when two of them clash.
You won't see any of that in a summary that says everything went well, so ask it to list the decisions and assumptions it made. Then quiz yourself. Pick a few lines at random and ask, what about this line? What about that one? For a document, close it and try to write out the main argument from memory. Some have a habit I like for long sessions: have Claude write a report on the change, and then give you a quiz at the bottom, where the rule is "I only merge after I pass the quiz perfectly."
Understand what you're shipping well enough to defend it. Because at some point, someone could ask.
Agents can also guard your attention. For example, I have an open source project that receives a lot of pull requests. I'll use agents to help determine what's incoming, what's contrary to our guidelines, and where my attention is likely required. I rarely let the agents self-determine this, but they can narrow it down to where I should focus my attention, and then I can actually think about whether these changes are solving the right problem in the right way.
Then there's volume, and you have to be honest with yourself about it. I've called this the orchestration tax. It's the gap between what your agents generate and what you'd feel comfortable putting your name on. If finished work is piling up faster than you can get through it, another session won't help until you've fixed that: tighten the checks so less of it needs you, or slow down.
When you're producing more than you can stand behind, you're no longer reviewing. You're hoping.
Quality in, quality out
The human mental model is still involved, but instead of in the middle, it's at the front and end. You're putting your energy into the front-end of the task description and context, as well as the back-end of reviewing the output. This is why good input is so important to the quality of output, and I view good prompting as a critical thinking skill.
Historically, if you made a non-specific request, someone would challenge it, and you might realize, "Oh wait, I actually didn't figure this out." An agent often won't stop you there. It fills in what you left out and hands back something that looks done, even though the idea behind it is still fuzzy. I've written about this as intent debt, the implicit goals, constraints and rationale that may exist in artifacts you didn't write. Unlike other kinds of debt, nobody else can fix this one for you. The intent has to come from you.
Your prompt is a reflection of your understanding of the problem, and if you can't express it clearly, it may not be clear in your own mind.
Write your own request brief in your own words before you ask for help. Describe the audience, out-of-scope items, and the definition of done. When your second round of corrections hasn't got you there, stop tweaking and rewrite your prompt.
You can have the agent help you with this too. I like the distinction Andy Clark makes between delegating to an AI system and collaborating with it. In the latter case, you're in a virtuous cycle of mutual amplification: your prompts sharpen your output, sharpen your next prompt and sharpen your mental model of the problem. If it's not clear, ask the agent to interview you about what it doesn't understand. If you close the session having refined your own mental model, that's a sign of success.
Also be careful about the input. It's easy for each agent to just pass the previous agent's summary into its context, and before long the third agent hasn't read the original document.
You also need your own standards for output. I've played around with AI in lots of different creative mediums, and most of it never gets shown because it doesn't meet my standards. Things are all coming out nicely formatted and confident, so polish is no longer a useful signal.
AI may have made it faster to produce, but if I wouldn't feel comfortable attributing the output to myself, I won't output it.
When something doesn't meet your standards, note why in shared config, a hook or a test so that it doesn't happen again. That's how taste compounds, and noting why something didn't make the cut is good practice on its own.
"But the models will be better at this than me"
If you're as bullish on the future of this space as many people around me are, you've probably had this thought for a couple of sections. In a year or two, the model will be able to detect what I'd be able to detect, so why bother maintaining the skill?
You may be right on a lot of that detection, and I've been arguing for increasingly pushing detection to agents myself. But here's why I think it still matters: at the end of the day, someone is responsible for what ships. Regardless of how much AI helped, a human has to take responsibility.
The question of how much to trust an agent for any given task is itself a judgment call. Part of staying calibrated is reviewing the work, because what the models get wrong keeps changing. Anthropic's own research on its engineers and researchers calls out the trap as the paradox of supervision: "supervising Claude requires the very coding skills that may atrophy from AI overuse."
These are some of the things that matter most to me and that a better model won't solve: what are you building, why is it worth it, who does it impact and what are you willing to sacrifice? Those are all questions you need to answer. An agent can be helpful in working them through, and I would like it to be, but ultimately they're still yours.
You may offload the work and much of the auditing, but not the accountability.
Practices for the everyday
You don't need to do all this rigorously. Just plug in what works for your workflow.
Once a week, write a bit of code without an agent, or do one real thing that would suck if you forgot how to do it. (I've called this a calibration exercise, but I don't mean it as a moral one.) Once a month, write down what you've stopped doing and decide which of those you're okay not doing. One question from an old blog post of mine remains as valid as ever: How lost would you be if AI didn't exist?
If something is above your comprehension, go learn it. If I'm writing and I run into a phrase I haven't seen before, I could Google a one-line explanation and include it. I prefer to do a little research to properly understand it, so I can see where it fits.
Checking the machine properly is real work, and pretending otherwise is how teams end up not doing it. It isn't free, so schedule it as a line item and you'll actually get it done.
Skills that you stop exercising are going to go away, and probably faster than you might guess. Keep doing the ones you're not willing to let go.
What to bring with you
- Be intentional. An agent can quiz you, interview you and show you its evidence, but only if you set that up. So set it up.
- Be honest about your place on the spectrum. If you can't explain the answer, even with an agent's help, you've surrendered it.
- Have a hypothesis. Formulate one before asking, even if it's bad.
- A green check means one thing. What did it check? What did it not check?
- Look for evidence. Read what it ran and what it returned before reading the summary.
- Read to know what decisions it made. What did it decide for you?
- Craft your prompt. How you write what you prompt shows how much you understood the problem.
- Set a bar, and stick to it. If you wouldn't put your name on it, it doesn't go out.
Keep yourself in the game by manually applying the skills that matter. One thing you could do: Before you ask, write down what you think will happen, and after the agent is done, write down one thing it didn't check. Let me know if that changes the way you read the output. Think independently. Ask better questions. Take responsibility for the outcome.
↑ 正文结束 ✓ 本篇全文免费开放
会员可复制、下载全文 Markdown,还能让你的 AI 订阅和提问。 订年卡 $59/年看权益对比 →
📮 新解读每晚进邮箱
读完觉得有用?留个邮箱,每晚一封当天的新解读,随时退订。